■ GPU cloud built and operated in the Emirates
The regional neocloud,
built for the UAE's AI era
Lion Neocloud is one platform for dedicated GPU servers, elastic GPU compute and in-region inference APIs — under one account, one bill and one line of support, with the latency your applications need and the data residency your regulators expect
UAEJurisdiction & Residency
LOCALRegional Latency
KYCVerified Customers Only
ONEAccount, Bill & Support Line
Why here  why now
Some markets adopt AI. This one planned for it.A national AI strategy years ahead of the curve, a region that ships its own models, and geography no other place can offer. We didn't choose this country from a list — for this platform, there was no list. why now 
The UAE made AI a matter of national strategy before most of the world noticed the race had started.The result is an ecosystem that builds and ships its own models — Falcon and Jais among them — not one that just consumes APIs from elsewhere.

Within close network reach of the Gulf, wider Middle East, Africa and South Asia — markets today served from datacentres continents away.Latency advantages built on geography don't erode. This one belongs to the Emirates alone.

Clear data-protection law and regulators fluent in technology: a jurisdiction where banks, healthcare and government don't just pilot AI — they put it in production.Trust is the region's infrastructure, and it's already built.
The platform
Three tiers, one platformDive as deep as the problem demands — bare metal, compute cloud, or a turnkey API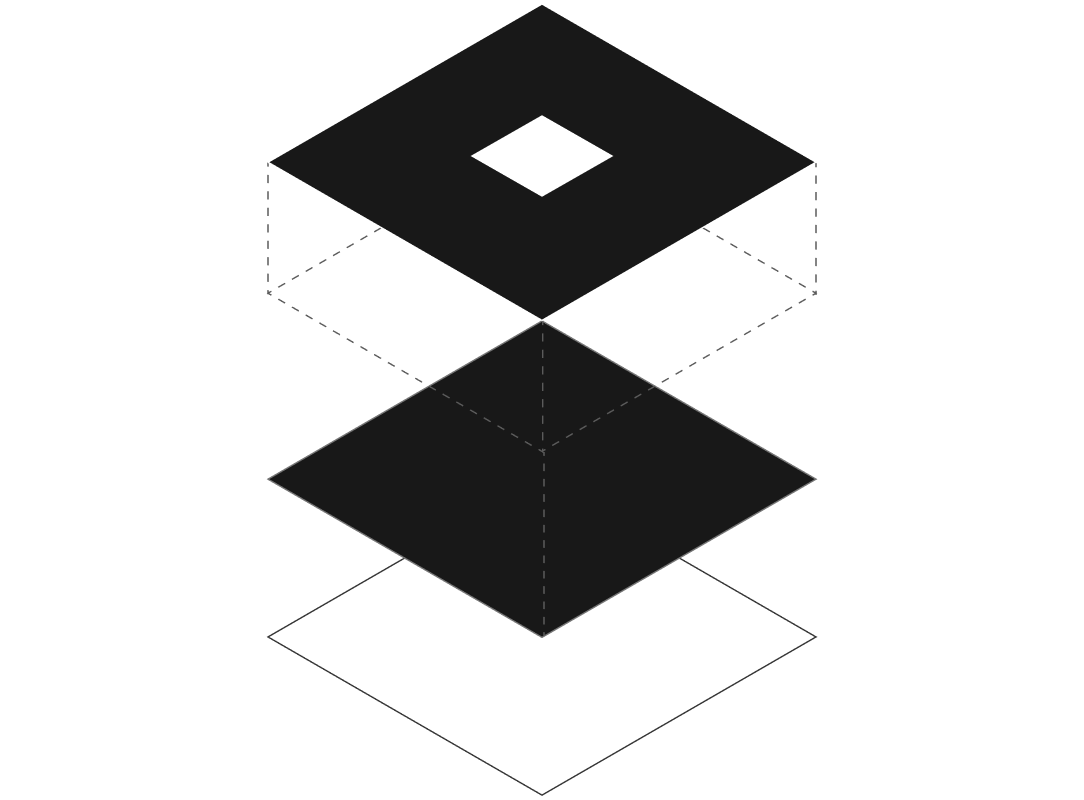
Tier 1
Bare MetalA dedicated GPU server that is yours alone: latest-generation NVIDIA accelerators, ready to log into within days, not months.- Direct SSH, your choice of OS, full root control
- Multi-node training and fast shared storage when one server is not enough
- You bring your stack; we watch the hardware, round the clock
Tier 2
GPU ComputeComputing power by the second, no machines to own or manage. Package your workload in a container and deploy — we run the rest.- Job queues with fair scheduling for research and batch work
- Multi-node runs; complete isolation from other tenants
- Pay for actual consumption — never for idle reservations
Tier 3
Inference APIReady-to-use AI models served in-region, priced by the token. OpenAI-compatible endpoints: switching to us is changing one URL.- Curated open-weight catalogue: Falcon, Jais and the world's leading open models
- Playground for a first try, API keys for production
- Bring your own model — served in-country, under your residency guarantee
Why us
Our approach Anyone can rent you GPUs. We built the platform around them — so you ship AI products, not infrastructure.01Self-service to the endFrom sign-up to production without a ticket, a salesperson, or an engineer in the loop
02You pay for what worksBilling starts only when your resource is verified available — never for a request, never for idle
03Every claim is provableResidency, uptime and every invoice line trace back to evidence — built for customers who answer to regulators
04Security by defaultAccess control, encryption, audit trails and round-the-clock incident response — not bolted on later
Who we serve
Built for the teams building AITraining models, shipping AI products, or serving a regulated market — there's a tier shaped for you Research teams & model developersTeams that need uncontended hardware and multi-node training — and run their own stack
Tier 1
 Startups & product teamsTeams that want to ship, not operate: containers in, results out, pay for what you use
Tier 2
 Regulated & public sectorBanks, insurers, healthcare, government — residency, verification and audit trails, by default
Tier 3
Roadmap
Where we are, and where we're headedFour stages, one directionPlatform designShaping the platform: the three tiers, the control plane, and the verification model behind them
Now
Platform design
Shaping the platform: the three tiers, the control plane, and the verification model behind them
Launch
First servers deliveredVerified early teams receive dedicated GPU servers — the rest of the platform is built around their live workloads.
First servers delivered
Verified early teams receive dedicated GPU servers — the rest of the platform is built around their live workloads.
Compute & inferenceGPU Compute and the Inference API open up — the full ladder on one account.
Expand
Compute & inference
GPU Compute and the Inference API open up — the full ladder on one account.
Open
General availabilityBroader regional launch once reliability and compliance are proven.
General availability
Broader regional launch once reliability and compliance are proven.
The future has an addressIt's being built in the Emirates right now.
Capacity goes to verified customers first — tell us what you're building.
Capacity goes to verified customers first — tell us what you're building.